Authors: Yuan Tang and Edward Tsien
Originally posted on Red Hat Research Blog.
Researchers and engineers from Red Hat and Purdue University have introduced VEX-Bench, the first benchmark for evaluating LLM agents’ ability to determine whether a known vulnerability in a third-party dependency is actually exploitable in a downstream software project. The work has been accepted for presentation at the Conference on Empirical Methods in Natural Language Processing (EMNLP), held October 24-29 in Budapest, Hungary. EMNLP is widely recognized as one of the premier, highly influential international tier-one venues for publishing peer-reviewed research in the fields of natural language processing and artificial intelligence.
Software composition analysis (SCA) tools such as GitHub Dependabot and OSV-Scanner help surface potential exposures by matching package names and versions against vulnerability databases. This approach is deliberately broad: it flags any project that carries an affected dependency version, regardless of whether the vulnerable code is ever reached. The result is a high volume of false alerts (in the VEX-Bench dataset, 70.7% of scanner-flagged cases are not exploitable in practice), and security analysts spend substantial time triaging them case by case. Reachability analysis partially addresses this, but determining whether a call path is feasible, and whether project configuration or runtime environment prevents exploitation, remains beyond current automated tools. LLM agents, with their ability to read code across repositories and reason about advisory text, are plausible candidates for this task, yet until now no benchmark existed to measure how well they perform it.
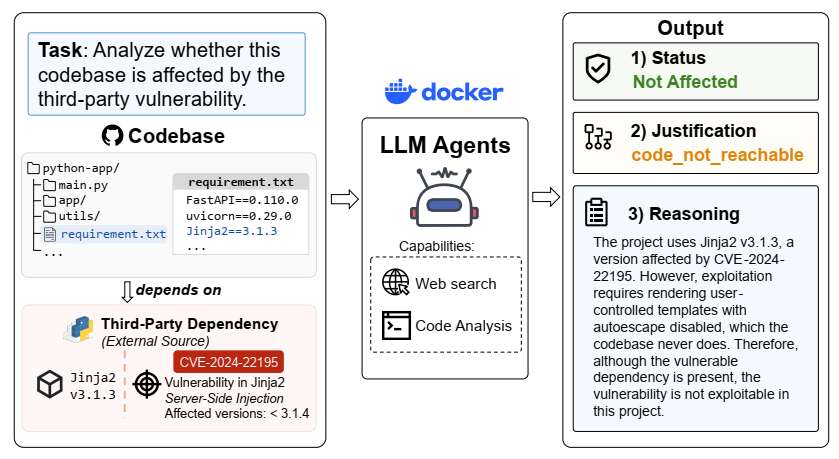 VEX-BENCH sources task instances from real-world projects by pairing codebases with third-party dependency vulnerabilities (CVEs) to determine real-world exploitability. Provided with the project’s source code and CVE identifier, LLM agents search external information and analyze code to produce a vulnerability status (Affected / Not Affected), a justification label (e.g., code_not_reachable), and reasoning grounded in the codebase.
VEX-Bench fills that gap with 75 real-world cases drawn from the top-starred open source repositories on GitHub, covering Go, Python, and Java. Each case pairs a target codebase with a CVE identifier for a known vulnerability in one of its third-party dependencies. The agent operates directly on the full project (a median of 273K lines of code across more than 2,600 files) with no curated file selection, no pre-computed call graph, and no advisory text beyond what it retrieves externally. It must produce a binary exploitability status and, when the verdict is Not Affected, a justification drawn from four categories adapted from the CISA Vulnerability Exploitability eXchange (VEX) vocabulary: “code_not_reachable”, “code_not_present”, “requires_configuration”, and “requires_environment”. Ground-truth labels were assigned by five security experts through a calibration-then-scaling annotation protocol, with an inter-annotator Fleiss’ Kappa of 0.667 at calibration and an 88.3% label agreement rate during the review phase. All experiments run inside isolated Docker containers with no access to benchmark labels, eliminating the possibility that agents circumvent the task by reading evaluation artifacts.
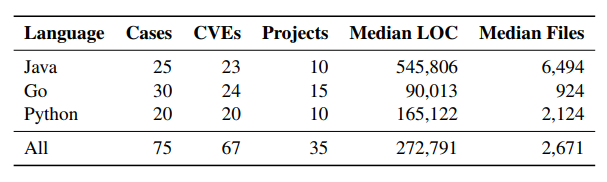 Dataset composition and codebase size across 75 cases, 67 CVEs, and 35 projects in Go, Python, and Java.
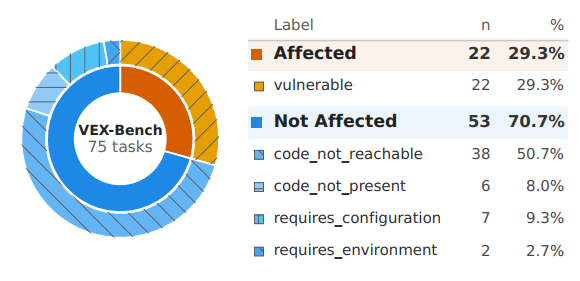 Binary vulnerability status distribution and fine-grained justification categories across benchmark cases.
The authors evaluated nine models, spanning both closed-source and open weight systems, across three agent harnesses: Claude Code, Codex CLI, and OpenCode. On the binary status task, Claude Opus 4.6 achieves the highest F1 of 81.6% and GPT-5.5 the highest precision at 88.7%; for fine-grained justification, only GPT-5.5 exceeds 70% macro-F1. By comparison, traditional SCA tools (OSV-Scanner, Trivy) achieve F1 scores of 40.5% and 36.1% in the same cases. This is the classic high recall but low precision that reflects precisely the false-alert burden practitioners experience.
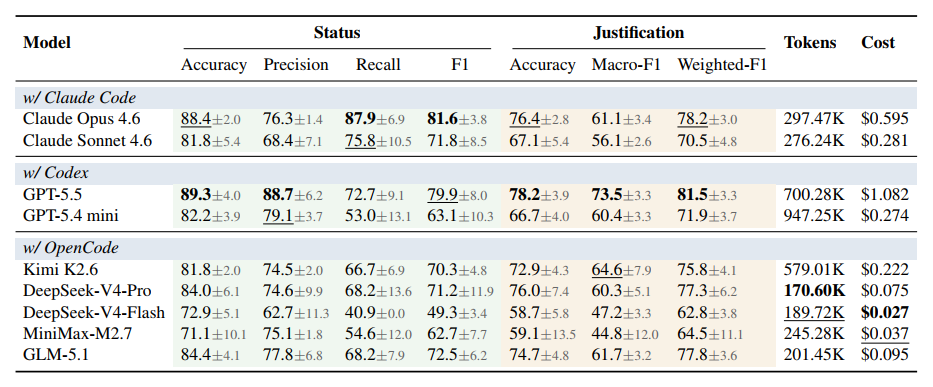 Performance metrics across nine models with token and cost averages.
Performance consistently drops from the binary to the justification task across all nine configurations, with gaps ranging from roughly 10 to 15 percentage points, indicating that current agents can identify affected projects with reasonable reliability but fall short of the depth of analysis needed to explain why a vulnerability is not exploitable. Among open weight models, DeepSeek-V4-Pro and GLM-5.1 offer accuracy within a few points of the top closed-source configurations at roughly one-tenth the inference cost. The harness framework was found to have a substantially larger effect on per-case token usage than on classification accuracy.
The paper is available on arXiv and will be available throughout the EMNLP 2026 proceedings. Code and data are available at https://github.com/steven1518/vex-bench.